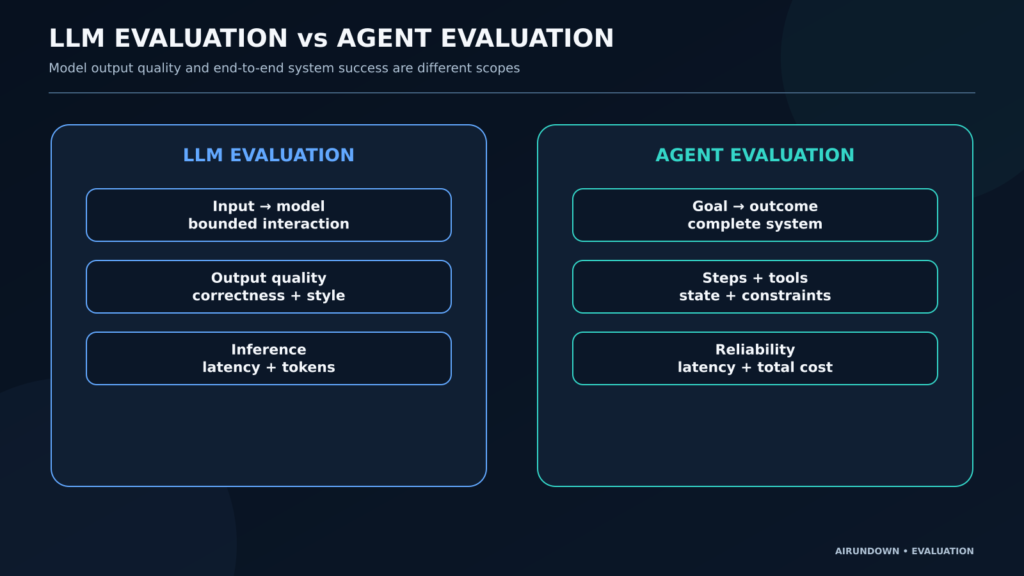
LLM Evaluation vs Agent Evaluation
LLM evaluation scores model outputs; agent evaluation measures the whole goal-directed system, including tools, state, constraints, reliability, latency, and cost.
Methods for evaluating AI agents, including task success, benchmarks, regression testing, LLM-as-judge approaches, and quality measurement.
LLM evaluation scores model outputs; agent evaluation measures the whole goal-directed system, including tools, state, constraints, reliability, latency, and cost.
3 published articles
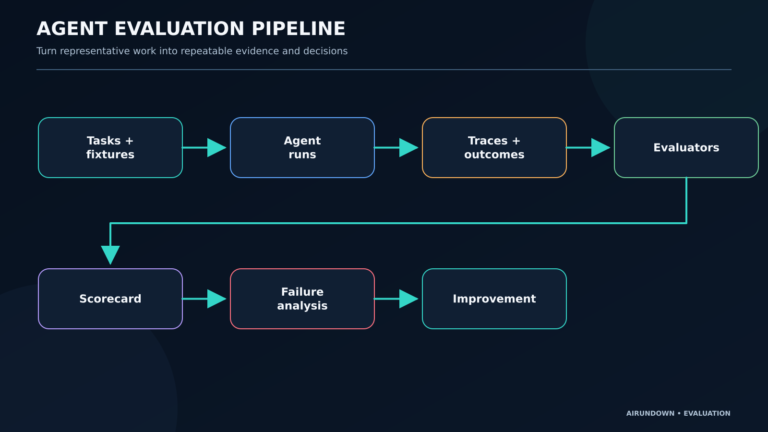
A practical workflow for defining agent success, building evaluation datasets, capturing traces, scoring behavior, analyzing failures, and preventing regressions.
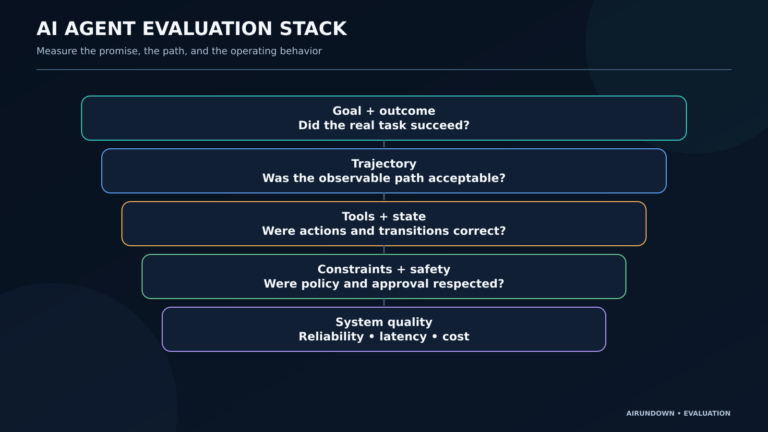
Agent evaluation measures task outcomes, trajectories, tool behavior, constraints, safety, reliability, latency, and cost—not only final prose.